Introduction
In this mini blog, we explore how different quantization formats (BF16, FP8 and NF4) affect the output of image generation AI models. These numerical formats determine how data is represented and processed, balancing precision, efficiency and memory usage.
BF16: high precision, moderate efficiency
BF16 (16-bit floating-point, Bfloat16 or Brain Float16, named because it was developed and used at Google Brain) is a 16-bit floating-point format that retains a wide range of values while reducing memory footprint compared to full 32-bit floats. It’s widely used in deep learning for its balance of precision and performance.
Bfloat16 is a custom 16-bit floating point representation that comprises one sign bit, eight exponent bits, and seven mantissa bits. The IEEE FP32 format uses 32 bits and the IEEE FP16 format uses 16 bits. Bfloat16 is a truncated version of the IEEE FP32 format, and uses the same number of exponent bits as FP32.
This enables a wider range of real numbers to be represented by BF16 compared to FP16, but with a lot less precision, as it has fewer bits to represent the data after the decimal point. Bfloat16 is used in deep learning frameworks because it has the same range as FP32 (with less precision after the decimal place) while using half the bits.
FP8: compact and fast
FP8 (8-bit floating-point) takes efficiency further by halving the memory usage of BF16. This compact format accelerates computation and reduces power consumption and memory use, though it sacrifices some precision, which may impact fine details in generated output.
NF4: optimized for neural networks
NF4 (4-bit Normal Float) is a highly specialized format designed for neural networks, offering extreme efficiency by using just 4 bits per value. It was introduced as part of the QLoRA paper: arxiv.org/abs/2305.14314.
While it excels in minimizing memory and compute costs, it requires careful optimization to maintain output quality, especially in complex image generation tasks.
Visual comparison: spot the difference
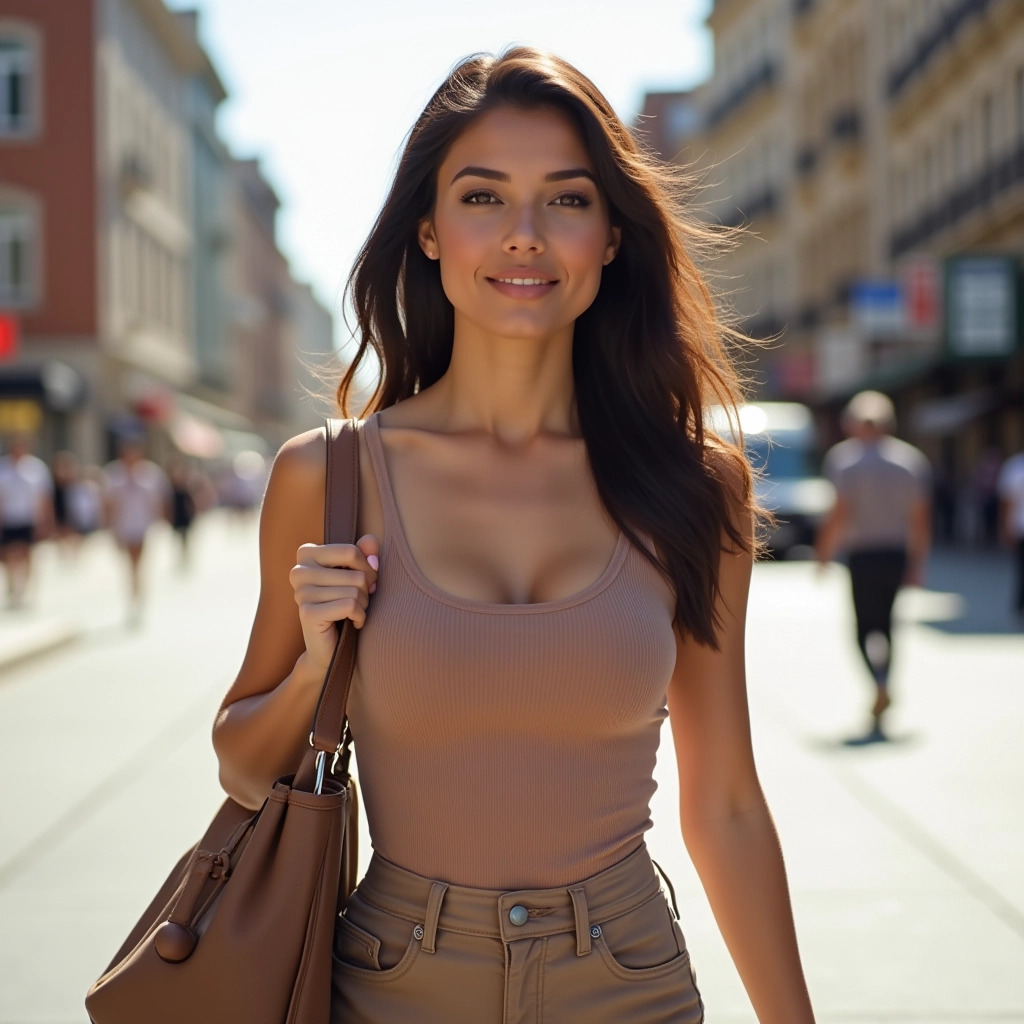
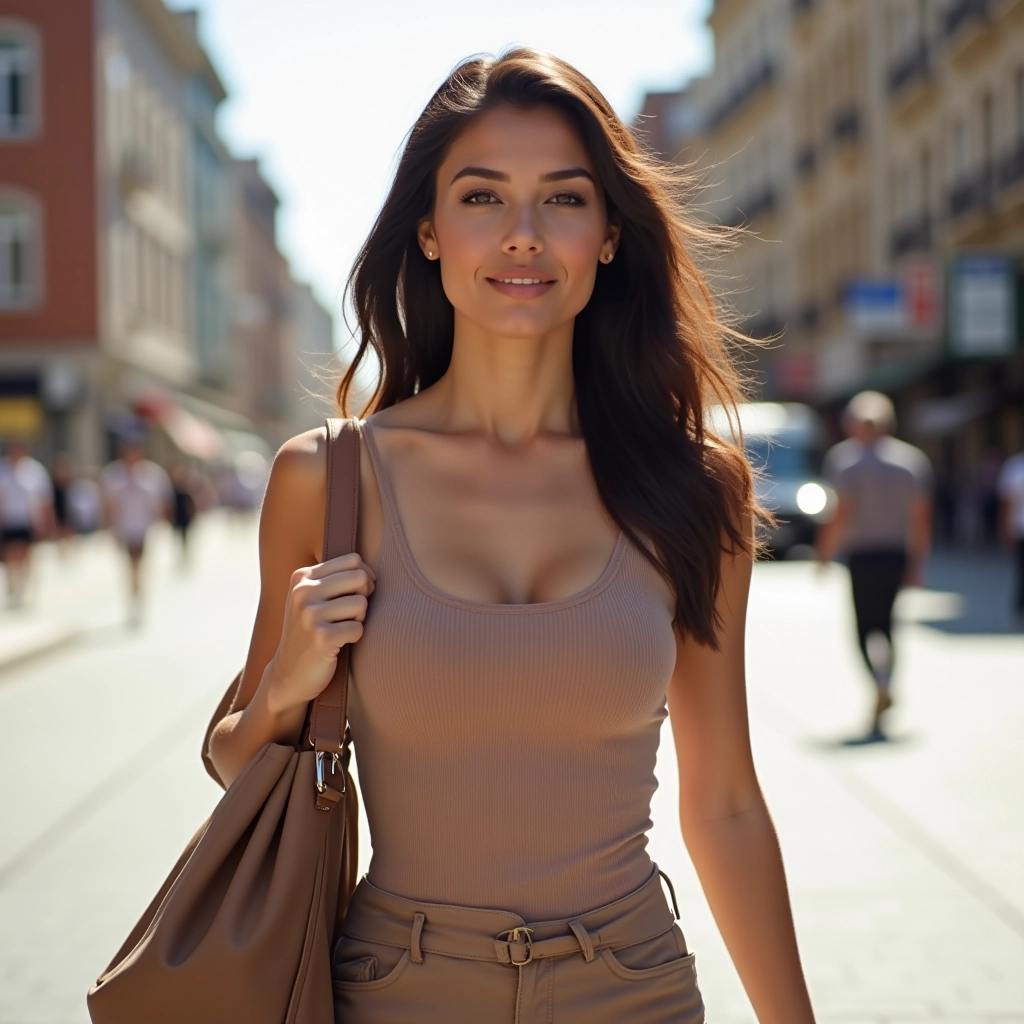
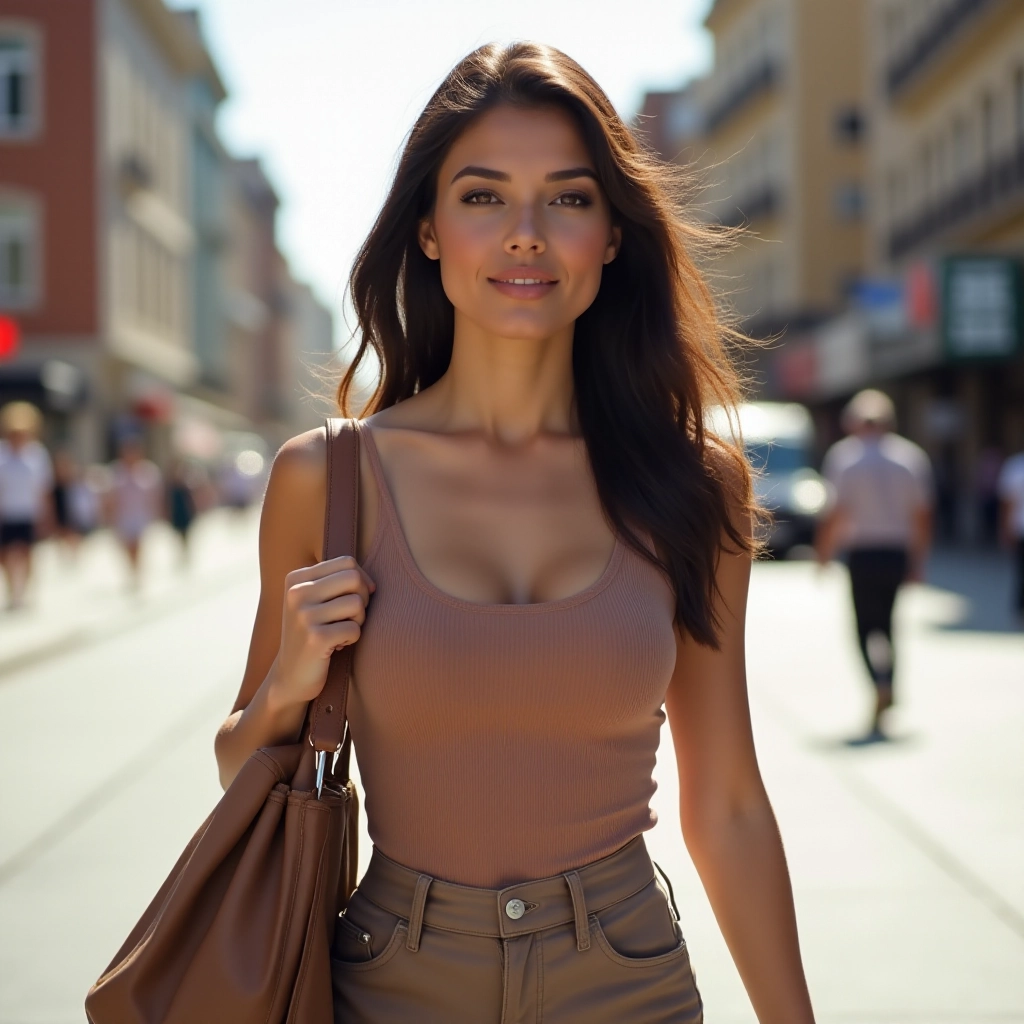
Conclusion
BF16, FP8 and NF4 each offer distinct trade-offs in image generation. BF16 provides robust precision for high-quality results using 16 bits, FP8 boosts speed and efficiency for resource-constrained environments using 8 bits, and NF4 pushes the boundaries of optimization by using just 4 bits per number.
The best choice depends on your project’s priorities: output fidelity, computational speed, or memory efficiency.
Additional notes
The original intent of this mini blog, in addition to the side-by-side results, was to also provide image generation times.
But while running timed generations, complexities related to the different representations used inside the CLIP and VAE models, and variable performance on different NVIDIA GPUs due to their internal architecture (after trying to focus on sampler iterations-per-second), led to significant variance in the results.